Claude 3.7 Sonnet vs GPT-4o Cost Audit (2026): Multi-Turn Agent & Prompt Cache Math
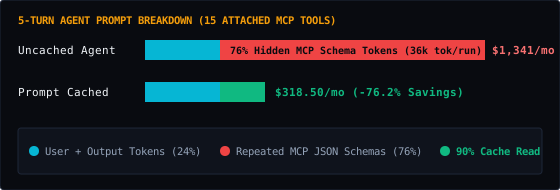
On uncached single-turn calls, GPT-4o ($2.50/1M in, $10/1M out) is 20%–33% cheaper than Claude 3.7 Sonnet ($3.00/1M in, $15/1M out). However, in a 6-turn Agent with 15 MCP tools (9,200 static prefix tokens) and an 85% cache hit rate, Claude 3.7 Sonnet's 90% cache read discount ($0.30/1M) vs GPT-4o's 50% discount ($1.25/1M) makes Claude 24% cheaper on input-heavy agent loops!
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 10,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 50,000 | $10.59 | $47.20 | $57.79/mo | $693.48/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 10,000 | $24.00 | $45.00 | $69.00/mo | $828.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 10,000 | $29.00 | $80.00 | $109.00/mo | $1,308.00/yr | Deploy → |
| Zapier (Professional Tier) | 40,000 | $29.99 | $1,511.13 | $1,541.12/mo | $18,493.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 60,180 tok | 34,200 tok | $18.60/mo | $56.90/mo |
| OpenAI GPT-4o-mini (OpenAI) | 63,780 tok | 37,800 tok | $32.60/mo | $75.69/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 62,880 tok | 36,900 tok | $36.90/mo | $106.63/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 62,880 tok | 36,900 tok | $74.35/mo | $214.90/mo |
| Claude 3.5 Haiku (Anthropic) | 69,180 tok | 43,200 tok | $81.22/mo | $288.46/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 66,480 tok | 40,500 tok | $256.16/mo | $572.14/mo |
Production cost trajectory modeled at 4 base nodes, 1 iterator items/run across 0 loop nodes, and 6 agent turns with 15 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (claude-3-7-sonnet) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 5,000 ops | $14.50 | $24.00 | $10.59 | $155.12 | $108.17 |
| 5,000 runs/mo | 25,000 ops | $14.50 | $39.00 | $28.29 | $771.12 | $540.86 |
| 10,000 runs/mo | 50,000 ops | $14.50 | $69.00 | $57.79 | $1,541.12 | $1,081.71 |
| 25,000 runs/mo | 125,000 ops | $14.50 | $159.00 | $146.29 | $3,851.12 | $2,704.28 |
| 50,000 runs/mo | 250,000 ops | $14.50 | $309.00 | $293.79 | $7,701.12 | $5,408.55 |
| 100,000 runs/mo | 500,000 ops | $14.50 | $609.00 | $588.79 | $15,401.12 | $10,817.10 |
Key Findings & Billing Mechanics
- Cache Read Asymmetry: Anthropic discounts cached input tokens by 90% ($3.00 -> $0.30/1M), whereas OpenAI discounts cached input tokens by 50% ($2.50 -> $1.25/1M).
- Extended Thinking Budget: Enabling Claude 3.7 Sonnet's `thinking` budget (e.g., 4,000 tokens) bills at the $15.00/1M output rate, adding $0.06 per turn if left uncapped.
Anthropic requires explicit `cache_control: { type: 'ephemeral' }` markers on the final tool definition and system block; forgetting the marker on your MCP tool array means 0% of your tool schemas get cached.
Production Architecture Recommendation
Use Claude 3.7 Sonnet with explicit `cache_control` breakpoints for high-frequency multi-step coding/SQL/MCP agents. Use GPT-4o when traffic is sporadic (<10 requests/hour) so you avoid Anthropic's 25% cache-write surcharge.