n8n vs Pipedream Pricing Audit (2026): Execution Credits vs 30s Memory Compute
Pipedream Advanced ($29/mo for 2,000 credits) is ideal for sub-5-second Node.js/Python webhook glue, where 1 run = 1 credit regardless of internal code loops. However, when calling slow Reasoning LLMs (DeepSeek-R1 / o3-mini taking 65 seconds) or raising worker memory to 1GB (4x multiplier), a single Pipedream invocation burns 12 credits ($0.12/run), making n8n Cloud ($0.006/run) 20x cheaper.
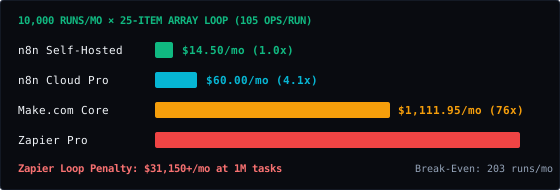
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 6,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 6,000 | $24.00 | $21.00 | $45.00/mo | $540.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 156,000 | $10.59 | $172.28 | $182.87/mo | $2,194.44/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 18,000 | $29.00 | $160.00 | $189.00/mo | $2,268.00/yr | Deploy → |
| Zapier (Professional Tier) | 150,000 | $29.99 | $5,746.13 | $5,776.12/mo | $69,313.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 8,300 tok | 3,040 tok | $1.71/mo | $11.91/mo |
| OpenAI GPT-4o-mini (OpenAI) | 8,620 tok | 3,360 tok | $2.27/mo | $12.81/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 8,540 tok | 3,280 tok | $3.35/mo | $21.95/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 8,540 tok | 3,280 tok | $6.79/mo | $44.11/mo |
| Claude 3.5 Haiku (Anthropic) | 9,100 tok | 3,840 tok | $10.14/mo | $72.10/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 8,860 tok | 3,600 tok | $17.82/mo | $95.11/mo |
Production cost trajectory modeled at 5 base nodes, 10 iterator items/run across 2 loop nodes, and 2 agent turns with 4 MCP tools attached:
| Monthly Scale | Total Operations (10x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-o3-mini) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 26,000 ops | $14.50 | $24.00 | $29.47 | $963.62 | $15.86 |
| 5,000 runs/mo | 130,000 ops | $14.50 | $39.00 | $152.19 | $4,813.62 | $79.26 |
| 10,000 runs/mo | 260,000 ops | $14.50 | $69.00 | $305.59 | $9,626.12 | $158.51 |
| 25,000 runs/mo | 650,000 ops | $14.50 | $159.00 | $765.79 | $24,063.62 | $396.28 |
| 50,000 runs/mo | 1,300,000 ops | $14.50 | $309.00 | $1,532.79 | $48,126.12 | $792.55 |
| 100,000 runs/mo | 2,600,000 ops | $14.50 | $609.00 | $3,066.79 | $96,251.12 | $1,585.10 |
Key Findings & Billing Mechanics
- The Wall-Clock Wait Penalty: Pipedream bills `ceil(execution_ms / 30000) * (memory_mb / 256)` credits. Waiting 62 seconds on an external LLM or Firecrawl job at 512MB RAM bills `3 * 2 = 6 credits` per run.
- n8n Wall-Clock Immunity: n8n Cloud does not multiply execution credits by wall-clock wait duration or step count.
Pipedream cold-start initialization on heavy npm packages (like Puppeteer or LangChain) counts toward execution wall-clock time when warm workers scale out.
Production Architecture Recommendation
Use Pipedream for fast (<10s), code-heavy TypeScript API transformations with 300+ built-in OAuth connectors. Use n8n for long-running AI Agent orchestration and human-in-the-loop waits.