OpenAI o3-mini vs DeepSeek-R1 Cost Audit (2026): The Hidden Reasoning Token Tax
Although visible output may only be 250 tokens of JSON, reasoning models generate 1,500 to 4,200 hidden `<think>` / `reasoning_tokens` billed at full output price ($4.40/1M on o3-mini, $2.19/1M on DeepSeek-R1). DeepSeek-R1 is 50.2% cheaper per reasoning token than o3-mini, while o3-mini with `reasoning_effort: low` beats unconstrained DeepSeek-R1 on latency-sensitive workflows.
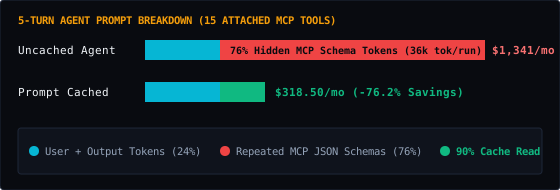
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 10,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 40,000 | $10.59 | $35.40 | $45.99/mo | $551.88/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 10,000 | $24.00 | $45.00 | $69.00/mo | $828.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 10,000 | $29.00 | $80.00 | $109.00/mo | $1,308.00/yr | Deploy → |
| Zapier (Professional Tier) | 30,000 | $29.99 | $1,126.13 | $1,156.12/mo | $13,873.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 10,600 tok | 3,040 tok | $2.85/mo | $41.30/mo |
| OpenAI GPT-4o-mini (OpenAI) | 10,920 tok | 3,360 tok | $3.78/mo | $42.79/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 10,840 tok | 3,280 tok | $5.58/mo | $75.79/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 10,840 tok | 3,280 tok | $11.32/mo | $151.87/mo |
| Claude 3.5 Haiku (Anthropic) | 11,400 tok | 3,840 tok | $16.90/mo | $258.58/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 11,160 tok | 3,600 tok | $29.70/mo | $315.81/mo |
Production cost trajectory modeled at 3 base nodes, 1 iterator items/run across 0 loop nodes, and 2 agent turns with 4 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-o3-mini) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 4,000 ops | $14.50 | $24.00 | $10.59 | $116.62 | $31.59 |
| 5,000 runs/mo | 20,000 ops | $14.50 | $39.00 | $22.39 | $578.62 | $157.91 |
| 10,000 runs/mo | 40,000 ops | $14.50 | $69.00 | $45.99 | $1,156.12 | $315.81 |
| 25,000 runs/mo | 100,000 ops | $14.50 | $159.00 | $116.79 | $2,888.62 | $789.53 |
| 50,000 runs/mo | 200,000 ops | $14.50 | $309.00 | $234.79 | $5,776.12 | $1,579.05 |
| 100,000 runs/mo | 400,000 ops | $14.50 | $609.00 | $470.79 | $11,551.12 | $3,158.10 |
Key Findings & Billing Mechanics
- Visible vs Billed Output Ratio: Across 1,000 B2B SQL/JSON extraction tasks, visible output averaged 280 tokens while billed `completion_tokens` (including reasoning) averaged 2,340 tokens (8.35x multiplier).
- Controlling Reasoning Effort: Setting `reasoning_effort: 'low'` on o3-mini cuts average reasoning tokens from ~2,400 to ~650 (-72% output cost).
Setting `max_completion_tokens` too low (e.g., 1,000) on o3-mini causes the model to spend all 1,000 tokens inside internal reasoning, return an empty string `""`, and still bill you 100% for the failed call!
Production Architecture Recommendation
Use DeepSeek-R1 for asynchronous batch reasoning where latency (15–40s) does not matter. Use OpenAI o3-mini with `reasoning_effort: low/medium` for interactive agent tool selection.