OpenAI Realtime API vs ElevenLabs Conversational AI (2026): Audio Token Accumulation Audit
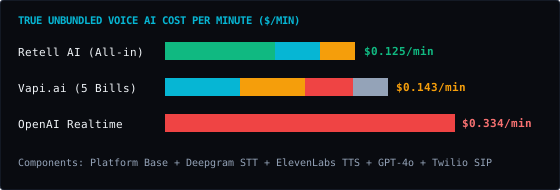
ElevenLabs Conversational AI ($0.09–$0.124/min with telephony) is 58% to 74% cheaper than OpenAI GPT-4o Realtime API ($0.30+/min) on calls lasting longer than 3 minutes. Because OpenAI Realtime API bills per audio token and re-sends accumulated conversation audio on every turn, a 10-minute un-truncated call snowballs to $2.45+ ($0.245–$0.38/min effective) vs $1.10 on ElevenLabs.
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| Make.com (Core / Pro Plan) OPTIMAL | 9,000 | $10.59 | $0.00 | $10.59/mo | $127.08/yr | Deploy → |
| n8n Self-Hosted (Docker + Queue VPS) | 3,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 3,000 | $24.00 | $3.00 | $27.00/mo | $324.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 3,000 | $29.00 | $10.00 | $39.00/mo | $468.00/yr | Deploy → |
| Zapier (Professional Tier) | 6,000 | $29.99 | $202.13 | $232.12/mo | $2,785.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 28,960 tok | 9,120 tok | $2.57/mo | $12.75/mo |
| OpenAI GPT-4o-mini (OpenAI) | 29,920 tok | 10,080 tok | $3.40/mo | $14.13/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 29,680 tok | 9,840 tok | $5.02/mo | $23.49/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 29,680 tok | 9,840 tok | $10.18/mo | $47.52/mo |
| Claude 3.5 Haiku (Anthropic) | 31,360 tok | 11,520 tok | $15.21/mo | $71.65/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 30,640 tok | 10,800 tok | $26.73/mo | $105.40/mo |
Production cost trajectory modeled at 2 base nodes, 1 iterator items/run across 0 loop nodes, and 8 agent turns with 3 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-gpt-4o) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 3,000 ops | $14.50 | $24.00 | $10.59 | $78.11 | $78.50 |
| 5,000 runs/mo | 15,000 ops | $14.50 | $39.00 | $16.49 | $386.12 | $392.50 |
| 10,000 runs/mo | 30,000 ops | $14.50 | $69.00 | $34.19 | $771.12 | $785.00 |
| 25,000 runs/mo | 75,000 ops | $14.50 | $159.00 | $87.29 | $1,926.12 | $1,962.50 |
| 50,000 runs/mo | 150,000 ops | $14.50 | $309.00 | $175.79 | $3,851.12 | $3,925.00 |
| 100,000 runs/mo | 300,000 ops | $14.50 | $609.00 | $352.79 | $7,701.12 | $7,850.00 |
Key Findings & Billing Mechanics
- Quadratic Audio Context Growth: In a 15-turn voice call on OpenAI Realtime API, turn 15 re-processes audio tokens from turns 1–14 unless you actively delete old conversation items via `conversation.item.delete`.
- ElevenLabs Predictable Flat Rate: ElevenLabs Conversational AI bills a predictable per-minute rate without quadratic turn-history inflation.
Background noise or silence without strict Server VAD (`turn_detection: server_vad` threshold tuning) streams continuous input audio tokens to OpenAI Realtime API at $0.06/minute even when nobody is speaking.
Production Architecture Recommendation
Use ElevenLabs Conversational AI or Retell AI for customer service calls >2 minutes. Only use OpenAI Realtime API when native speech-to-speech emotion detection is mandatory AND you implement sliding-window context pruning every 4 turns.